Happiness is better when shared—here’s a public resource site with tons of content

,

Not much to say, just check the ratings

ModelOC step-3.7-flash api.hcnsec.cn 评级 A 评分 95 风险 低 覆盖率 61.5% · 可信度 MEDIUM · 引擎 2.6.3 通过 10警告 1不确定 5 测试时间: 2026-08-03 18:27 UTC
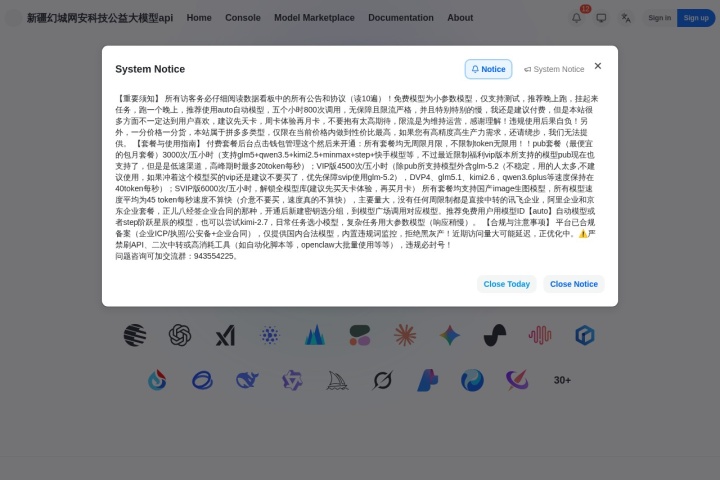
With aff link: 新疆幻城网安科技公益大模型API网关 | 免费GPT·Claude·Gemini接口

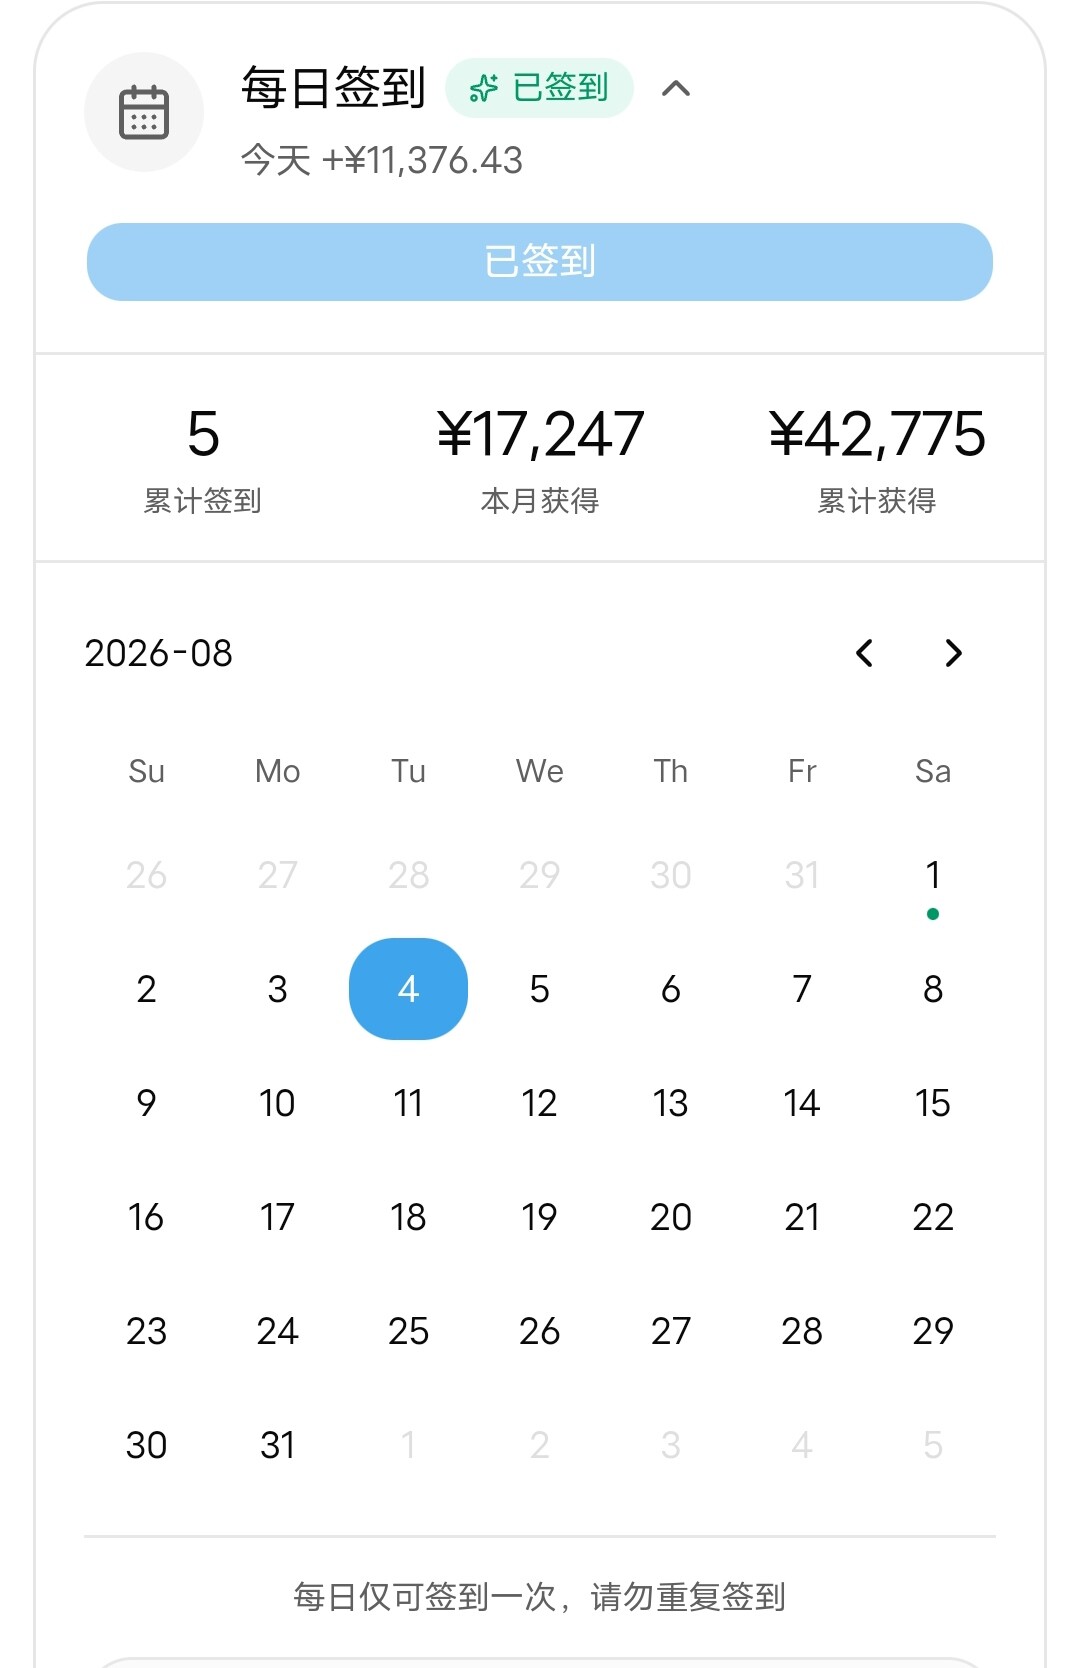
(Doesn’t matter, using this gives me just 2k, you get that just by checking in)

Without aff: 新疆幻城网安科技公益大模型API网关 | 免费GPT·Claude·Gemini接口

Signing up gives you a 29,000 quota, and you can check in as well
Most of the models are Chinese, but the sheer amount is unbeatable :ac01:
Some models like Qwen3.6-35B-A3B and step-3.7-flash are billed by usage (and step is really cheap, just official pricing), so you can use about 20-30B tokens a day

There’s also glm5.2, DeepSeek, etc., but those are pay-per-use—check if you need them; for me, not really worth it. (Otherwise, you can only check in a few hundred times)

Anyway, it should be more than enough for most people.

But be very careful—don’t use other weird models, like vector models or text-to-image models, they’re super expensive. Just using LLMs is more than enough!

(It seems the limit is 800 times in 5 hours, but whatever, you’re unlikely to hit that limit)

11 Likes

Another bug was found regarding the detection station’s model fingerprinting (the part where the model identifies itself).

It seems that models containing “think” weren’t properly handled, causing the reasoning process of inference models to be mistaken for response content, so it couldn’t be detected correctly.

This website is extremely slow—it’s basically unusable and absolutely unbearable. The only upside is that there’s a ton of content and it’s more than enough.

2 Likes

Already went aff, I’ll save this for later.

2 Likes

As long as there’s plenty and it’s filling, that’s enough—thanks for sharing.

1 Like

It’s really slow, but hey, it’s a public service—can’t ask for everything.

3 Likes

Thanks for sharing

Is it a fully domestic model?

1 Like

Okay, okay, it’s my fault, it’s my fault.

Alright, alright, it’s my fault, it’s my fault.

Thank you.

Uh :downcast_face_with_sweat:, I don’t think I ever recommended using per-use billing, did I?

I can’t believe people are still faking things at step 3.7 :xhj001:

And this one isn’t number one anymore, right? Isn’t it DeepSeek v4 flash 0731 now? (If that’s the case, just go to opencode, right? There’s plenty over there.)

And isn’t GLM’s strongest version supposed to be 5.2?

(Of course, that number is definitely inflated, but since the public site isn’t charging, can it really be called inflated?):ac01:

step and qwen are pretty fast, right? (Those are basically the only two I recommend—they’re cheap, fast, and can handle a lot.)

I don’t think I’ve recommended any other models, have I? :thinking:

It’s just an API at a glance, nothing to make a big deal about.

Alright, alright, it’s my bad, my bad.

The one in your previous image is the Inkling model, from Thinking Machines Lab.

Although the title mentions GPT, there’s actually no GPT.

1 Like

Where was it marked? I didn’t put any marks in my article, did I?

This model is pretty good for translation. Does this site support high concurrency?